

What exactly is Salesforce Data Skew?
If you've spent any time on enterprise-scale orgs, you've run into Salesforce Data Skew without realizing it at first. It's one of those silent killers that stays hidden until you try a big data load or change a sharing rule, and then everything breaks at once. It's what happens when your data isn't distributed evenly, creating "hotspots" that the system can't handle efficiently.
Think of a massive highway where every single car is trying to use the exact same exit at 5:00 PM. The highway itself is fine. That one exit ramp is a total nightmare. In Salesforce, those exit ramps are specific records or users that have way too many relationships tied to them, and once you hit that ceiling you start seeing the dreaded row-lock errors that keep us all up at night.
Understanding how to manage large data volumes is a huge part of being a senior architect, and skew is one specific flavor of that challenge.
The three main types of Salesforce Data Skew
Which one you're dealing with depends on how you built your data model. Here's how each shows up in a real project.
1. Ownership Skew
Probably the most common one I see. A single user or a queue owns a massive number of records, usually 10,000 or more. I've seen orgs where a "System User" owns 500,000 Accounts because the team didn't want to deal with ownership logic. When you update those records, Salesforce has to lock the owner's record to maintain integrity, so bulk updates run into lock contention faster than you can blink.
2. Lookup Skew
Lookup skew is a specific flavor of Salesforce Data Skew that happens when thousands of child records point to the same parent record. Imagine a "Generic Account" that every single orphan Contact gets linked to. Every time you add or change a Contact, Salesforce has to look at that parent Account, and once the parent has too many children the system struggles to maintain the indexes and sharing trees. Massive performance lags follow.
3. Sharing and Role Skew
Subtler than the other two, and just as dangerous. It happens when too many users sit in the same role, or when your sharing rules are so concentrated that a single change triggers a massive recalculation. Move one person at the top of a skewed hierarchy and Salesforce might have to rethink millions of sharing rows. That's when your deployments start timing out and your users start complaining that the system is "slow."
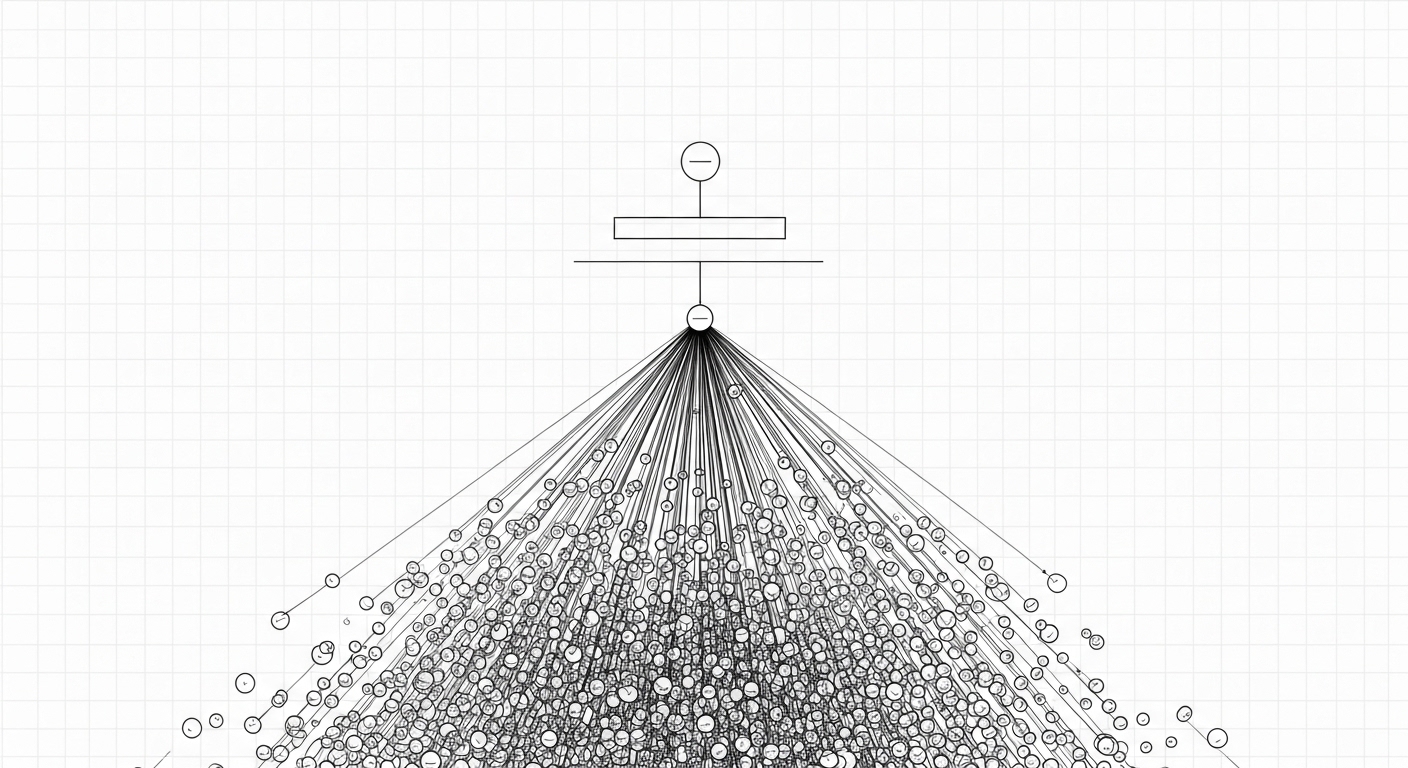
A technical architecture diagram showing a skewed data hierarchy where a single parent record is connected to a massive, dense cluster of child records.
How to spot the symptoms
Usually the system tells you, though not in a very friendly way. You'll start seeing "UNABLE_TO_LOCK_ROW" errors in your integration logs or Batch Apex results, which means your processes are fighting over the same record.
Another red flag is bulk data loads that take way longer than they used to. If a 50,000-record insert took ten minutes last month and takes an hour today, you might have a skew problem growing under the hood. You might also notice that simple updates to a parent record suddenly cause CPU spikes, because of the sheer volume of child records that need to be checked.
Pro tip: If you see a single user or parent record owning 10,000 or more records, you're officially in the danger zone. That's usually the threshold where Salesforce starts to sweat during sharing recalculations.
Detecting and fixing the mess
If you suspect you've got a problem, don't guess. Run some SOQL. A simple "Group By" query will find the culprits. For ownership skew, try something like this in your Query Editor:
SELECT OwnerId, COUNT(Id) FROM Account GROUP BY OwnerId ORDER BY COUNT(Id) DESC LIMIT 10
For lookup skew, just swap out the field for your lookup relationship. Once you've found the hotspots, you've got to start the cleanup. The fix for ownership skew is to distribute the load: use round-robin assignment, or spread records across multiple "integration users" instead of just one.
Lookup skew might mean rethinking your data model. Sometimes that's creating "overflow" parent records, sometimes it's using Async Apex to handle updates in smaller, manageable chunks. Honestly, most teams get this wrong by trying to fix it with code when the data architecture is what actually needs fixing.
Key takeaways
- Watch the 10k mark. Use it as your benchmark for when a relationship or owner is becoming a liability.
- Distribute ownership. Never let a single user own the world, and use queues or multiple service accounts.
- Pick your parents wisely. Avoid "dummy" records that act as a catch-all for lookups.
- Go async. Batch or Queueable Apex reduces the pressure on row locks during high-volume operations.
- Monitor regularly. Skew grows over time, so check your record distributions every few months.
Skew is a scaling problem, and it gets worse as the business grows. If you're seeing those locking errors today, take it as a warning. Look at your distribution, run your queries, and break up those hotspots before they turn into a full-blown system outage. It's much easier to fix a skew problem while it's small than to re-architect a live production environment with millions of records.
Leave a Comment