

If you've ever hit the dreaded SOQL limit while trying to pull a massive report or export, you know how much it can hurt your Salesforce query performance. You're trying to process a large dataset, and suddenly the platform throws a 50,001-row error in your face. It's frustrating, and there's a specific tool in the Apex toolkit that many developers overlook.
I'm talking about the @ReadOnly annotation. It's a simple little tag that bumps your query limit from 50,000 rows all the way up to 1,000,000. If you are already managing Salesforce large data volumes, this is one of the easiest ways to get a quick win.
What @ReadOnly actually does for Salesforce query performance
So what does this mean for your code? When you mark a method as @ReadOnly, you're telling Salesforce, "I promise I won't change anything; I just need to look at the data." Because you're giving up the ability to make changes, Salesforce relaxes the governor limits. It's a fair trade-off when you need to crunch numbers or build a heavy-duty dashboard.
One thing that trips people up is where you can actually use it. You can't just throw it on any old trigger or controller. It's designed for specific contexts like REST and SOAP web services, the Schedulable interface, and certain script-based entries. I've seen teams try to use it in triggers to bypass limits and get a compilation error for their trouble.
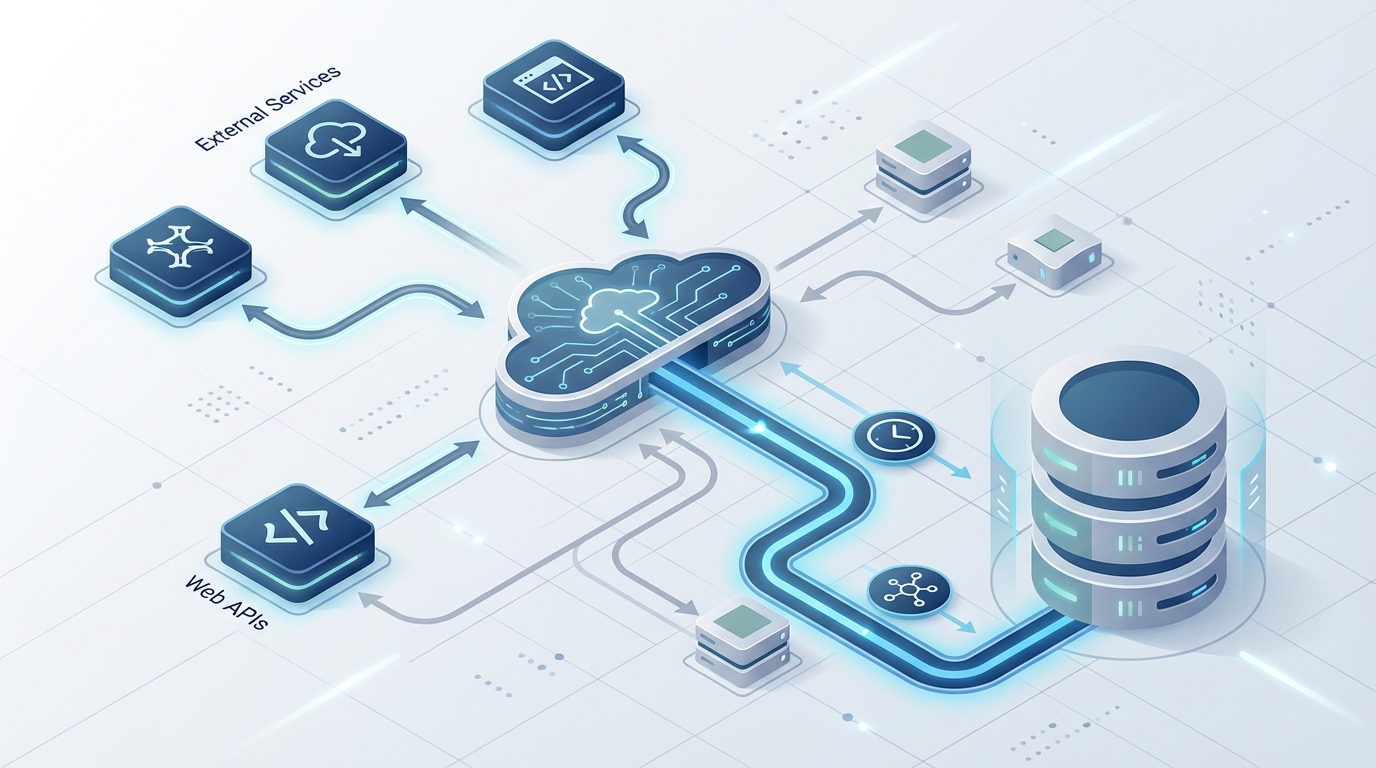
Architecture diagram of the data flow for scheduled jobs and web services in a Salesforce org.
The "No-Go" list: restrictions you can't ignore
There's no such thing as a free lunch in Salesforce. If you want that massive 1-million-row limit to boost your Salesforce query performance, you have to follow some strict rules. Here's the catch:
- No DML allowed. You can't insert, update, or delete a single record. If you even try to call
update myAcc;inside a read-only context, the whole thing will blow up. - No async calls. You can't fire off a
@futuremethod or enqueue a Queueable job. Salesforce wants to keep this transaction strictly about reading data. - Specific contexts only. It works best in web services, or when you're using the @AuraEnabled annotation for Lightning components, provided you set the cacheable attribute correctly.
If you find yourself needing to update records after reading a million rows, don't try to force it into one transaction. I usually suggest pulling the data in a read-only call and then passing the IDs to a separate Batch Apex job for the actual processing.
Best practices for Salesforce query performance and data handling
Just because you can query a million rows doesn't mean you should do it recklessly. I've seen developers write wide-open queries that eat up the heap limit before they even get to the 100,000th row. You still have to be smart about how you write your SOQL.
Always filter your queries as much as possible. Use indexed fields in your WHERE clause and only select the fields you actually need. If you're building something for a modern UI, you might also want to look into Apex Cursors to handle these big chunks of data more gracefully. The aim is to keep the overhead low while you get the most out of your Salesforce query performance.
Example: using @ReadOnly in a controller
Here is a quick look at how you'd actually set this up in a class. Notice how simple it is to implement once you have the right context.
public with sharing class DataExportController {
    @AuraEnabled(cacheable=true)
    @ReadOnly
    public static List<Account> getLargeAccountList() {
        // This can now return up to 1 million rows
        return [SELECT Id, Name, AnnualRevenue FROM Account WHERE CreatedDate = LAST_YEAR];
    }
}
The heap limit is still waiting for you, though. If those million rows are beefy records with dozens of fields, you'll run out of memory long before you hit the row limit. I always tell my junior devs: "The row limit is a ceiling, but the heap limit is the floor. Watch both."
Key takeaways
- The
@ReadOnlyannotation is your best friend for 1,000,000-row SOQL queries. - It completely forbids any DML operations (Insert, Update, Delete).
- It's built for reporting, analytics, and data exports where Salesforce query performance matters.
- You can't use it to trigger other asynchronous processes.
- Heap limits still apply, so don't query more fields than you need.
Honestly, most teams get this wrong by trying to use it in the wrong places. But if you're building a read-only integration or a heavy data dashboard, it's a lifesaver. It keeps your Salesforce query performance high without hitting those restrictive standard limits. Just remember to keep your logic clean and your queries selective.
Leave a Comment